
Internet of Things IoT Platform
Our client is a global Device-to-Cloud Internet of Things (IoT) technology company with a reach to nearly 750k developers and 20,000 business and enterprise customers, worldwide. Their mission is to
CHI Software provides Edge AI development services for real-time, on-device intelligence, model optimization, embedded AI, and edge-to-cloud integration.
Most artificial intelligence projects get stuck at the stage between a demo version running on a laptop and a model that functions reliably on a device in the field. CHI Software bridges this gap: we develop Edge AI computing solutions and provide services that integrate with real-world hardware, maintain their accuracy and continue to operate even without a network connection.




As an Edge AI solutions development company, we cover the full engineering path, from the first architecture conversation to a monitored production fleet. Every step is framed around what a CTO actually cares about: shorter AI time-to-production, deployments that do not break, code you can maintain, and technical debt that stays under control rather than compounding with each release. This is an edge AI development service built for teams that need results on the device, not another proof of concept that never leaves the slide deck.
We start with the target device, rather than a model. Together, we define acceptable latency thresholds, power consumption limits, connectivity assumptions and privacy requirements, and then design a ‘cloud-to-edge’ architecture that meets these requirements. You receive a clear technical plan and an objective assessment of the project’s feasibility before any funds are allocated for its development.
A preliminary proof of concept should answer one question: will it work well enough on the intended peripheral hardware? We build a specialised prototype, measure the speed and accuracy of inference on the actual target platform, and provide you with the data you need to make a decision – rather than a polished demonstration that hides the limitations.
Cloud ≠ devices. We take your model, or a proven open-source one, fine-tune it for your use case, and then make it fit the target hardware. We use quantization, pruning, knowledge distillation and hardware-specific acceleration. The result of applying AI model optimization techniques runs within the device’s memory, compute and power budget, with accuracy measured against the threshold your use case requires.
A model only earns its keep once it lives inside the product. Our engineers handle firmware integration on embedded systems, wiring inference into the device runtime, managing sensors and edge hardware, and testing behavior under real thermal and power conditions. See our embedded software development services for the wider hardware picture.
Edge and the cloud are not competitors. We integrate artificial intelligence embedded in devices with your server infrastructure to collect data for training, model updates and aggregated analytics, ensuring that each device remains ‘smart’ in its own right, whilst the entire fleet of devices continues to learn centrally.
Releasing the first version is the easiest part. Our services cover deployment pipelines on peripheral devices, OTA updates, device configuration and fleet management, and ensure continuous monitoring of model drift so that accuracy in the field does not decline imperceptibly after launch.
An Edge AI model that meets accuracy targets in the lab can fail on target hardware under real load. The gap is usually quantization loss, memory footprint, and inference latency on the actual device.
Get an Edge AI Feasibility AssessmentEdge AI systems is not the default answer. Centralized cloud inference is simpler to build and often the correct call. Processing near the data source earns its place only when one of these constraints is real and measurable.
When a decision has milliseconds to happen, a round trip to the cloud is too slow. Low-latency inference on the device is the difference between a car that brakes in time and one that does not.
Ships, mines, farms, and factory floors cannot assume a stable link. Offline AI keeps working through dropouts and syncs when the connection returns.
Keeping raw video, audio, or health data on the device means sensitive information never leaves it. That simplifies compliance and shrinks your attack surface.
Streaming every frame to the cloud is expensive. Running inference locally and sending only results cuts bandwidth and recurring cloud spend, sometimes by an order of magnitude.
On microcontrollers and small edge devices, TinyML and tight optimization let useful models run where a full cloud pipeline never could.
Legacy firmware built across multiple product generations blocks Edge AI integration at the driver and hardware abstraction layer. Mapping those constraints before model optimization starts prevents architecture rework mid-project.
Map Your Legacy Constraints Before Integration StartsEdge AI applications span on-device computer vision for object detection, tracking, and video analytics: think quality inspection on a line, people counting in a store, or safety monitoring on a site. Our Edge AI services cover the development and deployment of these vision solutions, with frames processed on edge hardware so that only relevant events reach your servers.
Sensors on machinery generate data on vibration, temperature and acoustic parameters faster than any cloud-based system can process it cost-effectively. We apply Edge Intelligence: anomaly detection and predictive maintenance models, identifying a faulty bearing before it brings the production line to a halt.
Voice commands, transcription and small language models that operate without sending speech data to a server. Processing data directly on the hardware (on-device AI) ensures the confidentiality of conversations and fast response times, even in offline mode, which is crucial in cars and regulated environments.
We turn plain IoT devices into ones that reason locally. Working across gateways, sensors, and constrained hardware, we add edge intelligence so the network reacts in real time instead of waiting on a central server.
Robots and autonomous systems require perception systems and control loops that never stop, thanks to cloud services. We are building a powerful, low-latency intelligent system at the edge, on which these platforms rely to perceive their environment, make decisions and act safely, all independently.
We define the use case, the target device and the success metrics. Completion criteria: agreed-upon targets for latency, accuracy and cost, as well as a clear “yes” or “no” answer regarding technical feasibility.
CHI Software develops an ‘edge-to-cloud’ architecture and tests high-risk components at an early stage. The completion criterion is a prototype that meets the target hardware performance metrics, with integration dependencies identified in advance rather than discovered later. For NPU-equipped hardware, as part of our broader services, we apply hardware-specific acceleration that delivers a 10x or greater reduction in inference latency compared to CPU-only execution at the same power envelope.
We optimize and then deploy models for your target hardware. The completion criterion is that the accuracy and inference speed must meet the target values on the actual device, rather than on an emulator.
Our team integrates output algorithms into embedded software and conducts real-world testing – provide full device provisioning. The criterion for completion is stable operation across a range of temperatures, at different power levels and under various connection conditions, with reliability being measured rather than taken for granted.
CHI Software rolls out updates via OTA and the device fleet management system as part of its Edge AI services. And then monitors any model discrepancies. Completion criterion: a controlled roll-out with a viable update path and a maintenance plan, for which the client is responsible.
Edge AI in medical devices and automotive systems falls under EU AI Act high-risk classification. Deterministic behavior, audit trails, and explainability need to be in the architecture from day one, not retrofitted during certification review.
See How Compliance Is Built Into Edge AI Delivery| Category | Technologies |
| AI & ML Frameworks | TensorFlow Lite, PyTorch, ONNX Runtime, MediaPipe, llama.cpp / MLC LLM |
| Model Optimization | TensorRT, OpenVINO, TVM, PyTorch Live, ExecuTorch, Neural Magic |
| Edge Hardware | NVIDIA Jetson, Qualcomm, NXP, Raspberry Pi, Google Coral TPU, STM32, Apple Neural Engine |
| Embedded Platforms | Embedded Linux, FreeRTOS, Zephyr |
| Cloud & Edge | AWS IoT, Azure IoT Edge, Docker, Kubernetes, MLflow, Snowflake |
| Languages | Python, C, C++, Rust, Go, Swift / Kotlin |
Our client is a global Device-to-Cloud Internet of Things (IoT) technology company with a reach to nearly 750k developers and 20,000 business and enterprise customers, worldwide. Their mission is to
Cutting-edge AI indoor navigation system for construction: suggesting GPS alternatives for precise movements inside buildings.
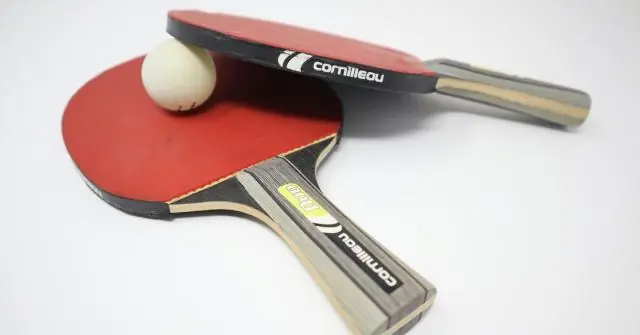
Innovative table tennis video analysis on iOS and Android! AI identifies game highlights, longest rallies, and offers multi-angle insights.






Operationalizing edge AI takes more than a model. It needs AI, embedded, cloud, data, DevOps, and MLOps skills in one team. That combination is what separates an edge AI development company that ships from one that stops at the demo. As an edge AI development firm, working since 2013 in embedded systems and since 2017 in AI, we bring these capabilities and services together under one roof. When a project runs on aging device software, our track record as a legacy software modernization company ensures a safe migration. When you just need extra hands, you can hire embedded engineers to extend your own team.
Our AI engineers and embedded engineers sit on the same team, so model decisions account for hardware limits from day one instead of surfacing as a nasty surprise during integration.
We tailor models to the specific silicon chips on which they will run, using quantization, pruning, distillation and hardware acceleration to achieve the specified latency and memory usage metrics on the exact system you supply.
From data processing pipelines to on-device inference to backend analytics, we build the whole loop. That keeps edge and cloud consistent and spares you the work of stitching together several vendors.
We view edge deployment as a beginning, not an end. Our services cover OTA updates, device configuration, fleet management and anomaly monitoring to ensure the accuracy and ease of maintenance of your AI edge systems long after launch – it is at this stage that technical debt is usually hidden.
Beyond isolated inference, we build multi-agent edge systems where devices coordinate decisions in real time (NXP eIQ Agentic AI Framework, Arm distributed agents). A defect triggers not just an alert but an action: the system consults a local knowledge base, logs to the backend, and adjusts production parameters, all without a cloud round trip.
The CHI Software team successfully developed upgraded versions of the company's products with new functionalities and features. Thanks to these contributions, the company was able to increase its number of platform users and deepen the level of their engagement.
Founder at Albert AB

CHI Software Team were involved in the whole SDLC, including design development, implementation and maintenance of new and/or existing application systems. We had an excellent experience working with them so far.
CTO at BetterTradeOffPteLtd
CHI Software played a crucial role in optimizing our mobile application, ensuring seamless functionality across iOS and Android platforms. Initially brought in for a short-term fix, their expertise quickly became indispensable as they resolved critical publishing issues, modernized outdated libraries, and enhanced navigation. Their proactive approach in identifying and fixing hidden flaws significantly improved app stability and usability. CHI Software’s adaptability, deep technical knowledge, and ability to streamline a previously fragmented system have made them a trusted technology partner in this project’s success.
Lead Data Engineer at Cefetra Group B.V.
We have been working with CHI Software for several years and have always had a very positive experience. Their team is reliable, responsive, and quick to understand our needs, which is especially important when we have urgent or challenging hiring needs. I really appreciate how easy they are to work with, their flexibility, and how quickly they respond and adapt when priorities change. CHI Software has been a great partner for us, and we look forward to continuing our cooperation.
Recruitment Team Lead at Company NDA
We have an in-house technical team but we needed a partner who could perform development in fields that we couldn’t cover. CHI Software has designed and developed an iOS and Android app, including its server backend and the site crawler it uses — it’s a big part of our system. They took the solution from an MVP to its final stage. We’ve been very satisfied with the team, they are very good in terms of planning, project management and customer care.
CEO at Democra.C
CHI Software supported us in developing several innovative products, including an AI-driven scientific research platform, a stock market analytics application, and automation solutions for business operations. The team delivered new product modules, improved platform performance, and helped establish scalable technical foundations. Their expertise in AI, cloud technologies, and modern software development made them a reliable partner for complex projects.
Chief Executive Officer at Digis
At Imagine Learning, we highly value our collaboration with CHI Software. Their skilled AI and generative AI engineers have significantly enhanced our K–12 education solutions.
With CHI Software’s help, we have developed tools for providing feedback on student writing, mechanisms to create learning content based on reading education strategies, and a series of chatbots that provide efficient and accurate information access for our teams. Their ability to deliver specialized applications swiftly demonstrates their agility.
VP, Product Management, AI Initiatives at Imagine Learning
Hardware selection and model optimization decisions made early in an Edge AI project determine latency, power draw, and maintenance cost across the product's entire lifecycle.
Request an Edge AI Architecture Review
Edge AI runs machine learning models directly on a device, a camera, a sensor, a gateway, or a vehicle, instead of sending data to a remote server. The device processes information and acts on it locally, which cuts latency and keeps data in place. Our Edge AI services help businesses design, deploy and optimize these solutions for real-world applications.
Cloud-based artificial intelligence sends data to central servers for inference; edge artificial intelligence performs inference directly on the machine. Edge computing ensures that data is processed exactly where it is generated. Cloud-based solutions are suitable for resource-intensive training and large models. Edge solutions are the better choice when speed, privacy, offline operation or reduced bandwidth costs are required. Most real-world systems utilise both approaches. Our Edge AI services help design and implement the right balance between cloud and edge computing based on your specific requirements.
Use cloud-to-edge architecture when you are forced to do so by practical constraints: the need to make decisions in milliseconds, an unreliable connection, data that must not leave the device, high bandwidth costs, or hardware that is too limited for a cloud pipeline. If none of these factors apply to your situation, cloud inference is usually the simpler option. As part of our Edge AI development services, we assess these constraints and help determine the most suitable deployment architecture for your use case.
From tiny microcontrollers based on TinyML to modules such as NVIDIA Jetson, Qualcomm, NXP, STM32 and Raspberry Pi. The right choice depends on your requirements in terms of accuracy, latency, power consumption and cost, and we will help you weigh up all these factors during the requirements analysis phase. Our Edge AI engineering services cover hardware selection, requirements analysis and deployment planning to ensure the chosen platform fits your technical and business constraints.
As an Edge AI development firm, we use quantization, pruning and knowledge distillation to reduce the size of the models and speed up their performance, and then apply hardware acceleration for the target chip. The aim is to stay within the constraints on computational resources and memory, whilst maintaining the accuracy required for your use case. These optimisation techniques are part of our Edge AI model optimisation services, helping prepare models for efficient execution on resource-constrained devices.
The cost depends on the machine, the complexity of the model and the stage you are currently at. A proof of concept (PoC) with a clearly defined scope of work represents a small, fixed investment; a full-scale production implementation will be more expensive. Please contact our edge AI services development team, and we will calculate the cost, taking into account your objectives and constraints.

About cookies on this site